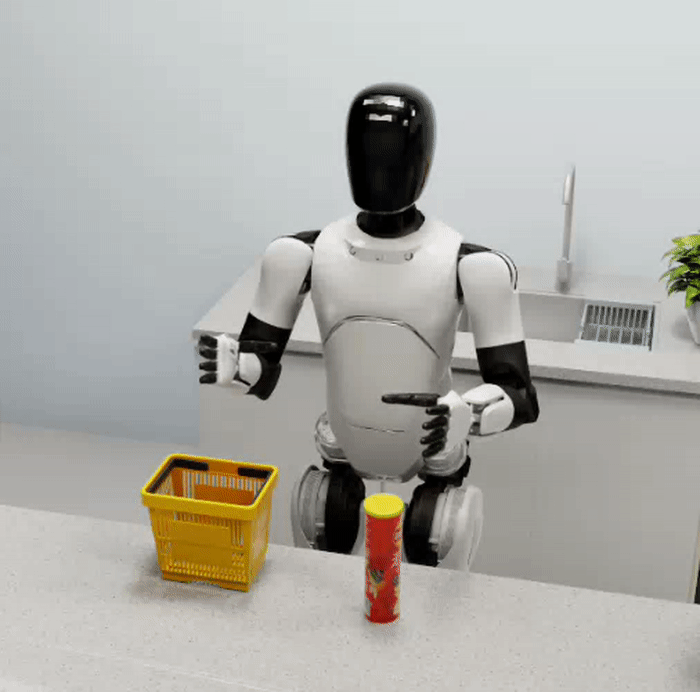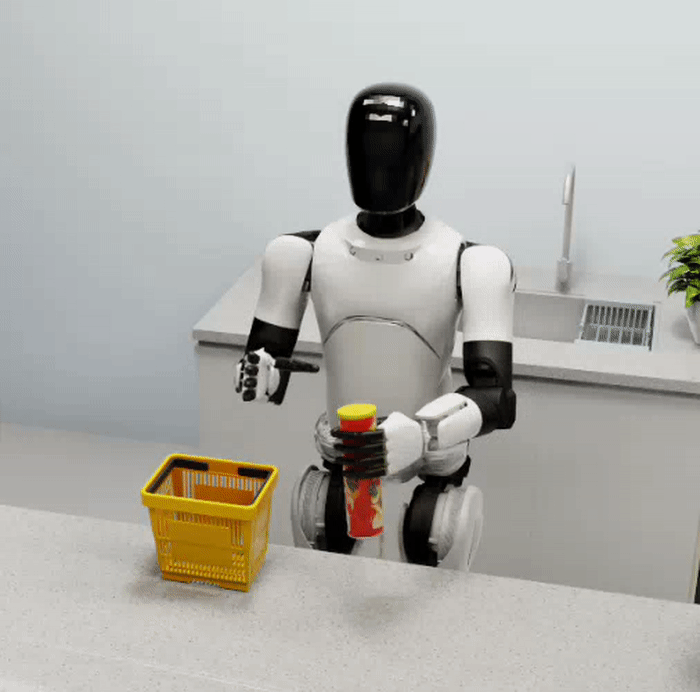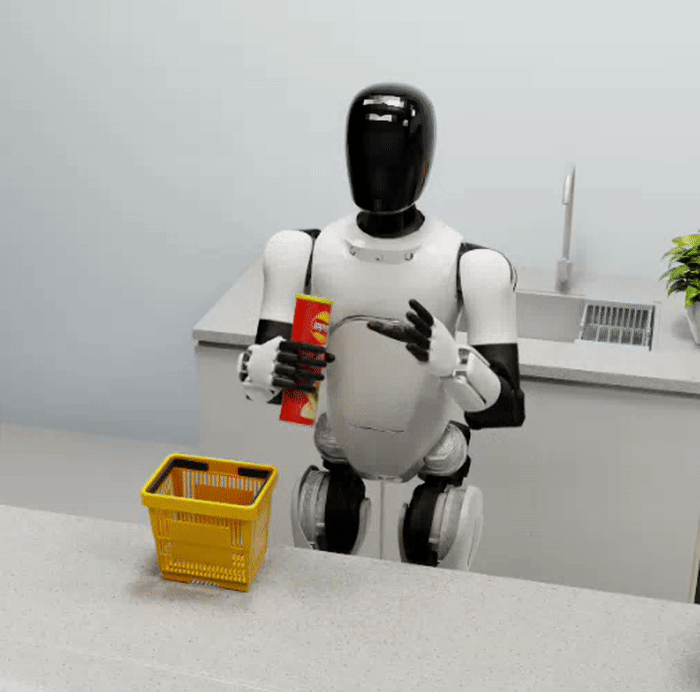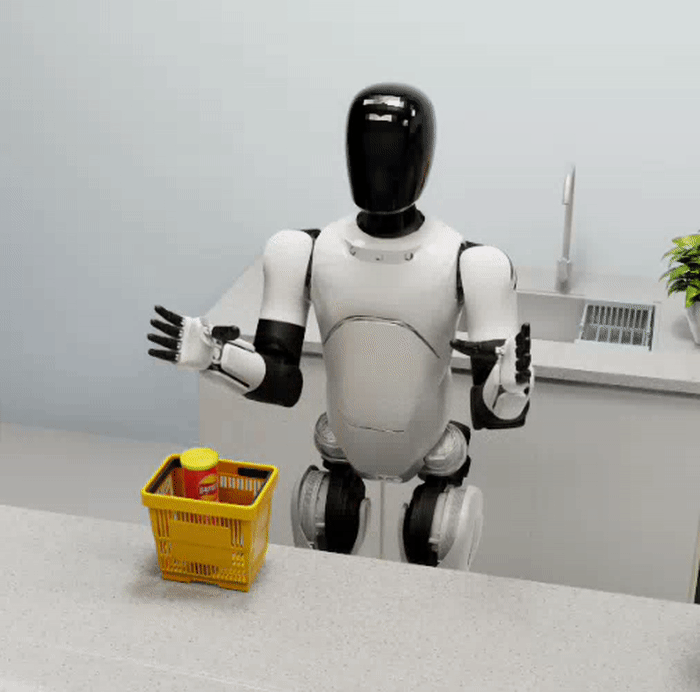
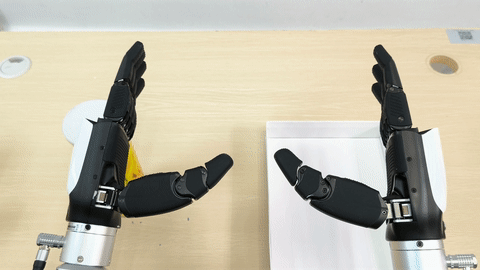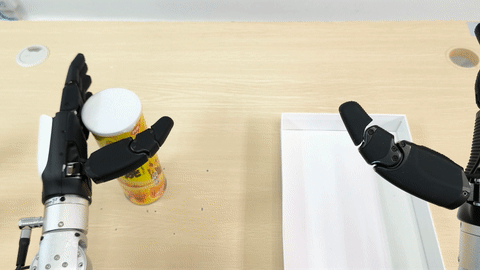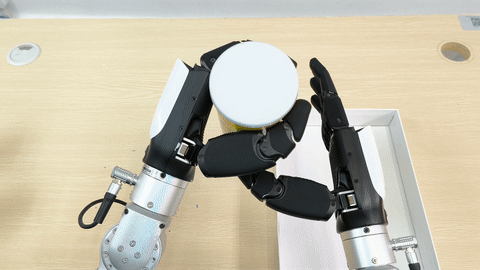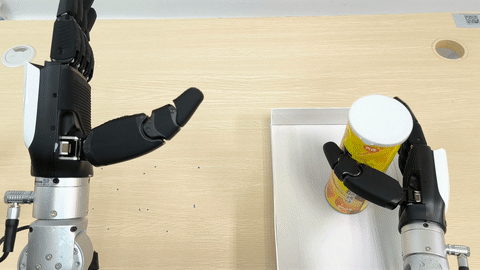
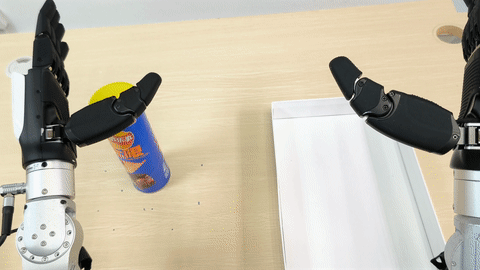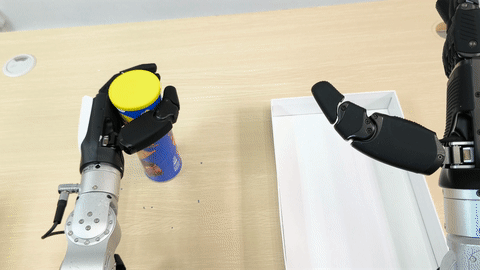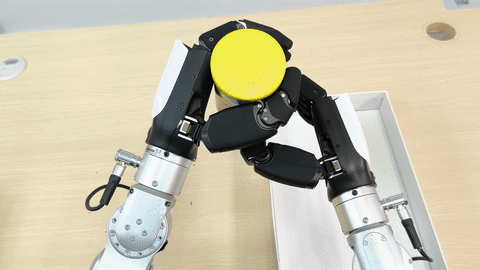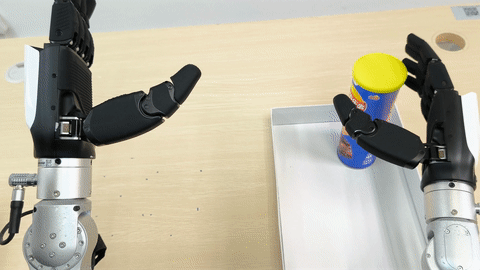
Self-Evolving Data Engine · Parallel Worlds Expansion

Seed2Scale

A Self-Evolving Data Engine with Parallel Worlds Expansion
for Scalable Robot Learning

Cong Tai†·Zhaoyu Zheng†·Haixu Long†·Hansheng Wu†·Jialiang Wang·Zhengbin Long
Haodong Xiang·Shuyuan Wang·Rong Shi·Zhuo Cui·Shizhuang Zhang
He Wang·Biao Liu·Zhenzhe Sun·Tao Shen*

ZTE Corporation, China
† Equal contribution * Corresponding author

Existing data generation methods for robot learning suffer from limited exploration, embodiment gaps, low signal-to-noise ratios, and domain shifts, leading to performance degradation during self-iteration and poor generalization to unseen scenes. We propose Seed2Scale, a self-evolving data engine with parallel worlds expansion. Starting with as few as four seed demonstrations, Seed2Scale first executes a self-evolution stage driven by a heterogeneous synergy of "small-model collection, large-model evaluation, and target-model learning", then projects self-evolved trajectories into parallel worlds for visual generalization — achieving a 75.38% success rate in zero-shot real-world evaluations, where baseline methods fail completely (0%).
 Paper PDF  Demo Video  RealMirror Platform  BibTeX
0%
Zero-Shot Real-World Success
0%
Unseen-Scene Success (from 0%)
0
Seed Demos Required
26.3 Hz
SuperTiny Control Freq.
SCROLL
01 — Abstract

Breaking the
Data Bottleneck

A dual-stage self-evolving framework that generates massive, high-quality robot trajectories from minimal human input — and projects them into parallel worlds for real-world transfer.

SEED SYNERGY SCALE

The emergence of Vision-Language-Action (VLA) models is accelerating the evolution of Embodied AI. However, the performance of these models remains strictly contingent upon large-scale, high-quality expert demonstration trajectories, creating a critical "data scarcity" bottleneck that fundamentally obstructs the scaling of robot learning.

To address this, we propose Seed2Scale, a self-evolving data engine with parallel worlds expansion, operating through a dual-stage pipeline. In the self-evolution stage, a lightweight SuperTiny collector (πsmall) enables robust exploration from only 4 seed trajectories, a frozen Qwen3-VL verifier (ΦVLV) autonomously scores and filters trajectories to prevent model collapse, and a SmolVLA target model (πtarget) learns exclusively from curated trajectories. In the parallel worlds stage, self-evolved trajectories are projected into diverse environments of the same task, enhancing adaptability to unseen scenes and real-world deployment.

Experiments demonstrate consistent scaling as iterations progress. The self-evolution stage lifts Seen-scene success from 22.18% to 68.57%, while Parallel Worlds raises Unseen-scene success from 0% to 65.34%. Notably, Seed2Scale achieves a 75.38% success rate in zero-shot real-world evaluations, where baseline methods fail completely (0%). Code, datasets, assets, and model weights will be open-sourced.

02 — Overview Video

Display Video

A comprehensive demonstration of the Seed2Scale pipeline — from seed data collection to self-evolution, parallel worlds expansion, and zero-shot real-world deployment.

03 — Framework

The Seed2Scale Pipeline

From 4 boundary-point demonstrations to massive high-quality training data — a dual-stage self-evolving ecosystem combining self-evolution with parallel worlds expansion.
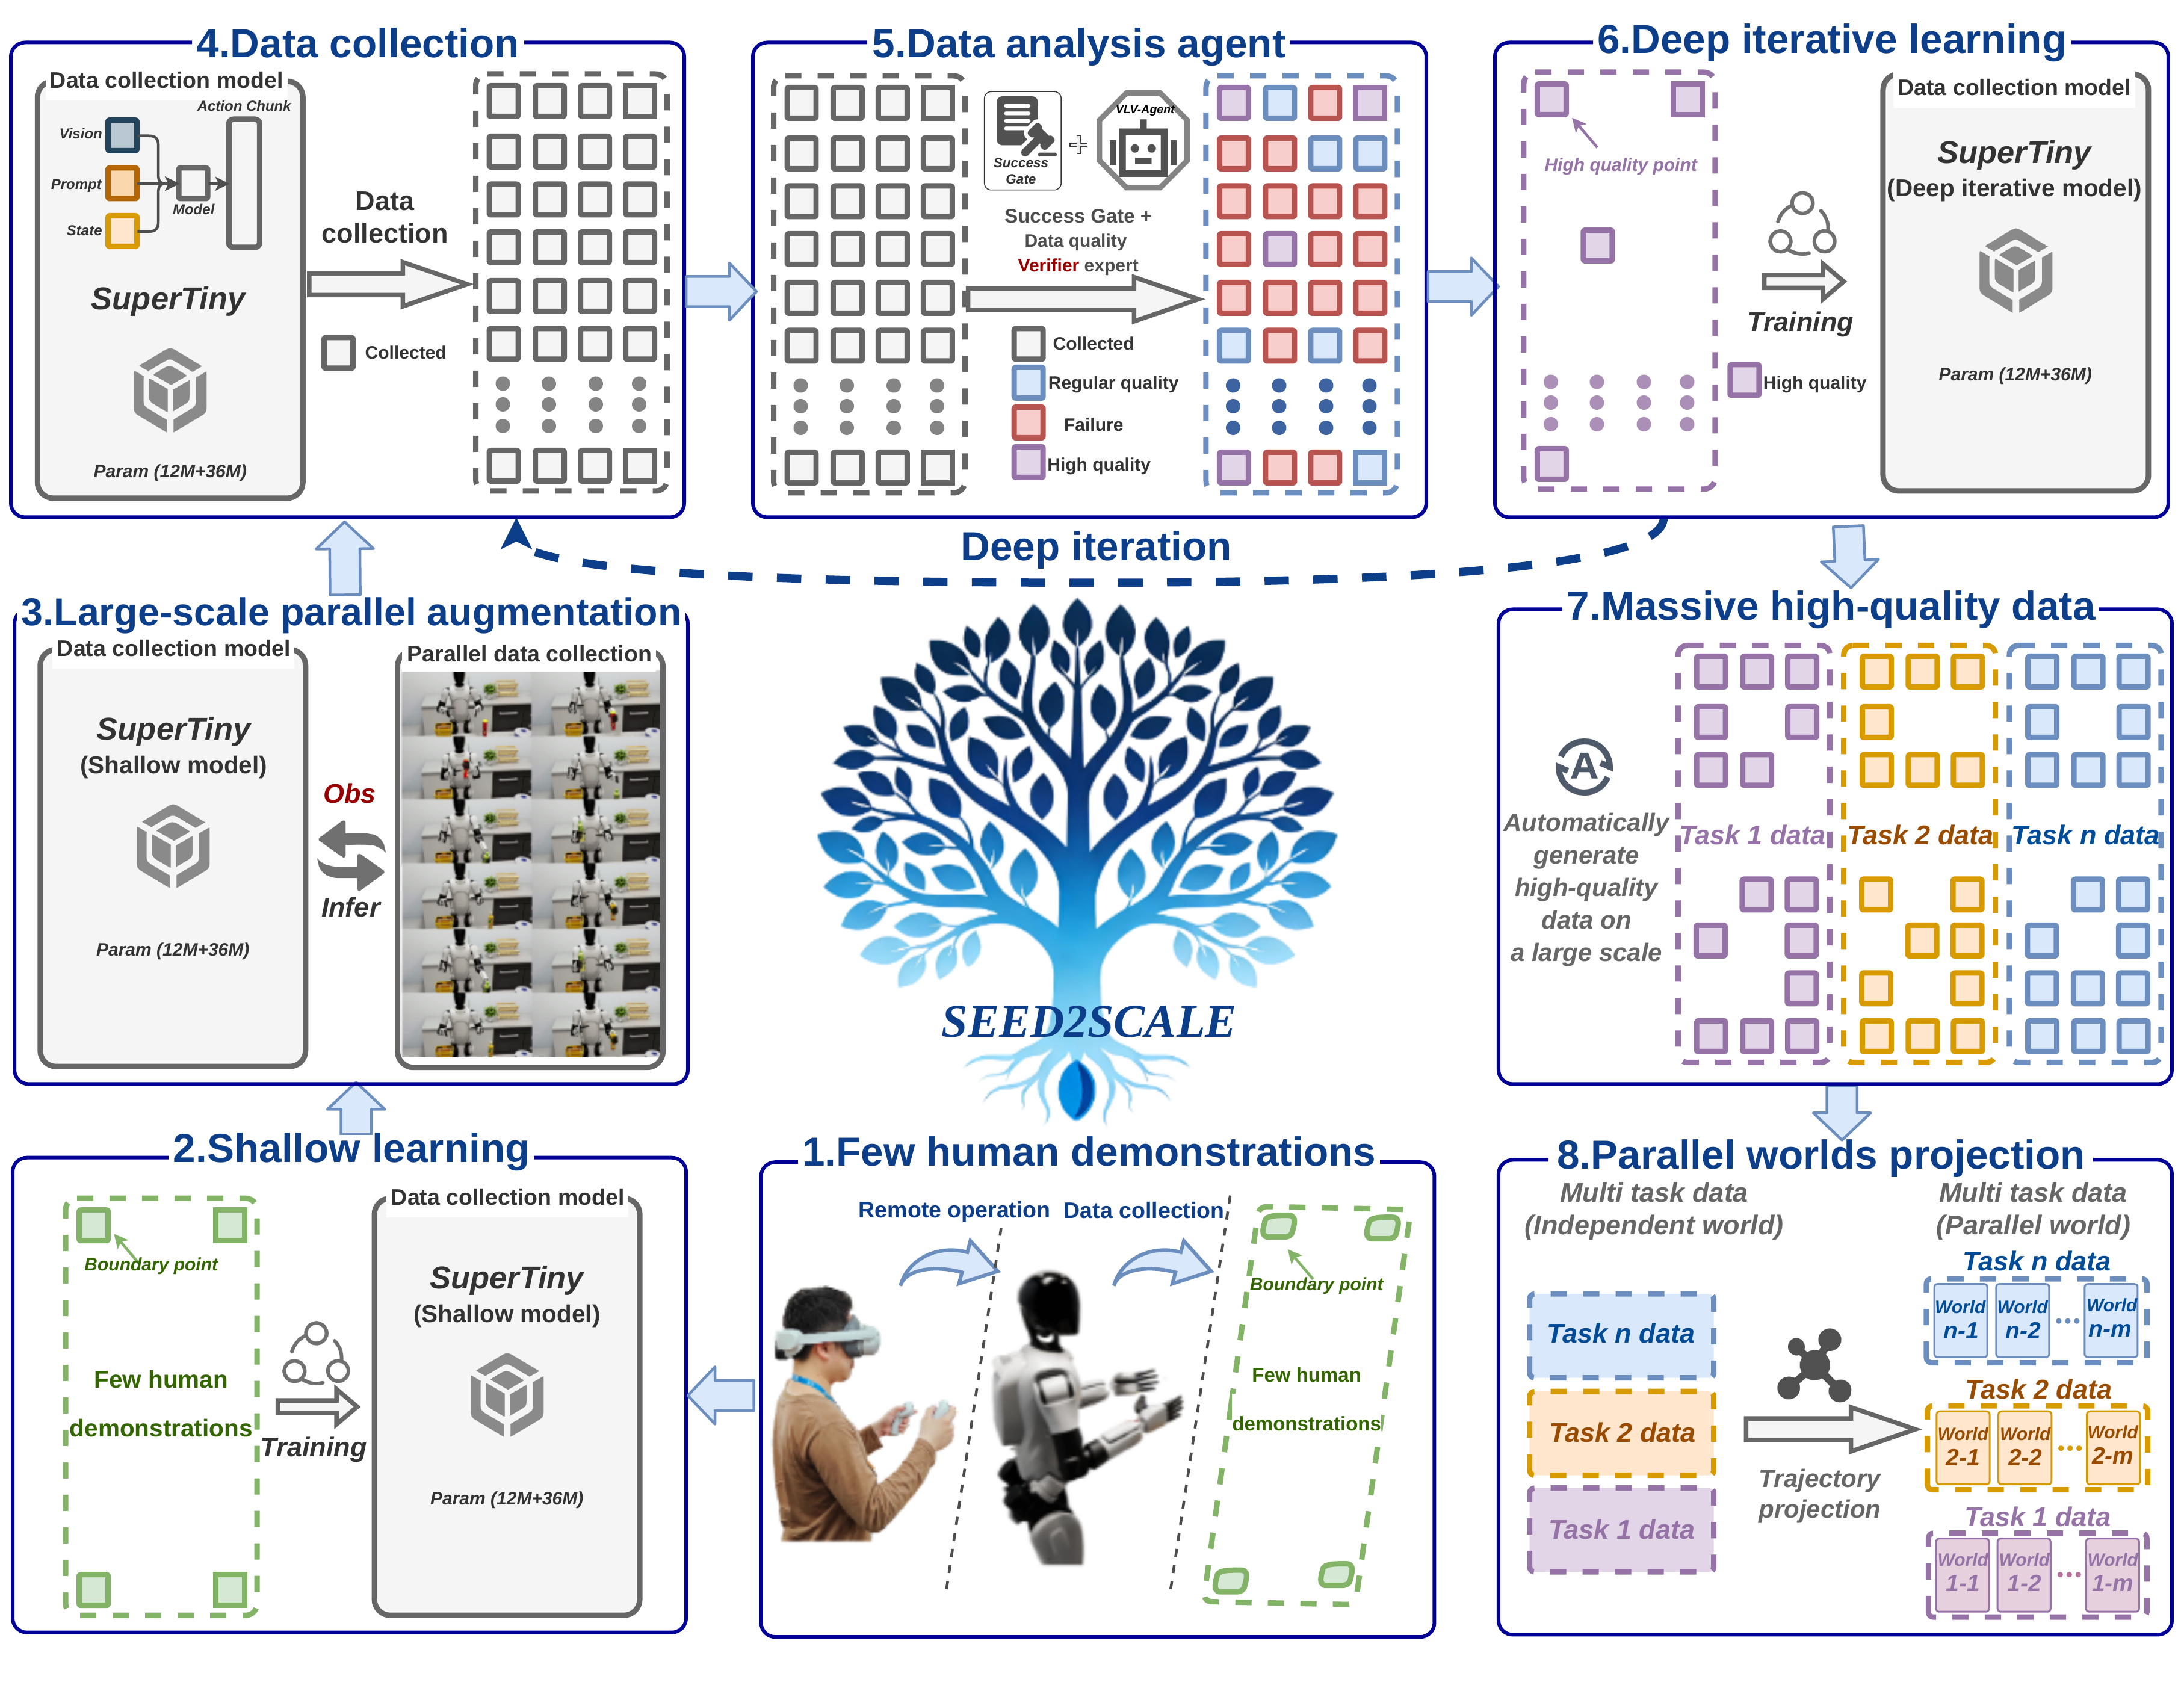
Seed2Scale self-evolving data engine pipeline overview with parallel worlds projection
Fig. 1 — The Seed2Scale self-evolving data engine. Starting with as few as four human demonstrations, the framework utilizes a lightweight SuperTiny VLA model for large-scale parallel data collection. A pretrained Vision-Language Model acts as a Verifier, autonomously scoring and filtering the raw trajectories to prevent model collapse. A parallel-world projection mechanism then achieves visual generalization on top of the position generalization accomplished through self-evolution, yielding large-scale, high-quality, and diverse datasets for model training.
04 — Methodology

Heterogeneous Synergy + Parallel Worlds

Three specialized model roles and one trajectory-level augmentation stage, each exploiting distinct scale asymmetries to achieve what no single model can accomplish alone.

SuperTiny Collector

A lightweight 48M-parameter VLA model: a ResNet-18 vision encoder, frozen T5-Small language encoder, and a compact MLP state embedding are unified into a conditioning memory, processed by a query-based Transformer decoder with action chunking (K=30) and temporal ensembling. Achieves 26.3 Hz inference — 3.6× faster than Diffusion Policy — and bootstraps robustly from just 4 seed trajectories.

πsmall · 48M params · 26.3 Hz

VLM-as-a-Verifier

A two-stage verification pipeline: a rule-based success gate filters failed trajectories by design, then a frozen Qwen3-VL-32B serves as the Vision-Language Verifier (VLV), scoring execution quality from the task instruction, rollout video, and a reference demo. Only trajectories with Sτ ≥ γ enter Dsilver, preventing data-poisoning spirals.

ΦVLV · Qwen3-VL-32B · Frozen

Parallel Worlds

A trajectory-conditioned stage that projects self-evolved trajectories into diverse target worlds of the same task — with task-relevant objects at source-aligned poses but varied assets, backgrounds, and cameras. Feasibility checks (workspace, kinematics, collision, contact, smoothness) precede re-collection, and VLV-filtered rollouts augment the final dataset.

Trajectory projection · 10 worlds · 3DGS

SmolVLA Target Model

The final policy (πtarget) trained via Conditional Flow Matching on the curated dataset Dfinal. Its Action Expert architecture interleaves Cross-Attention (CA) over vision-language context with Self-Attention (SA) for temporal coherence — enabling stable closed-loop deployment on Agibot A2 and GR-1 robots.

πtarget · 450M params · Flow Matching
Dual-Stage Pipeline: Self-Evolution → Parallel Worlds

4 Seed Demos

Boundary-point teleoperation

SuperTiny

Parallel rollout N envs

Gate + VLV

Rule gate + score S ≥ γ

Dsilver

Curated trajectories

Parallel Worlds

Project τ into M target worlds

Dfinal → SmolVLA

Target model training

05 — Qualitative Results

Task Demonstrations

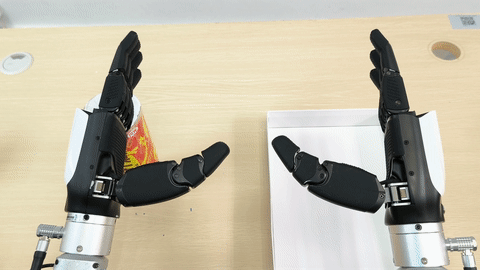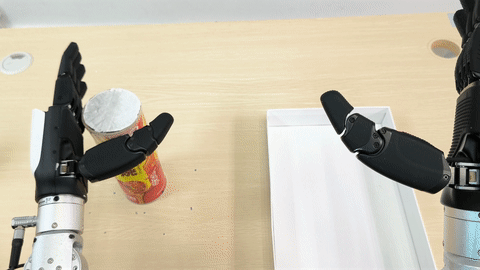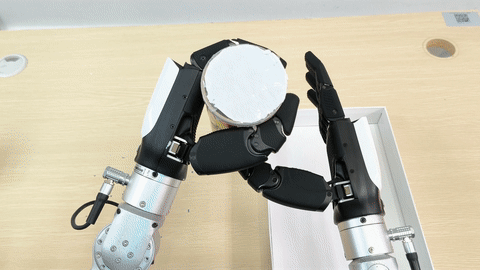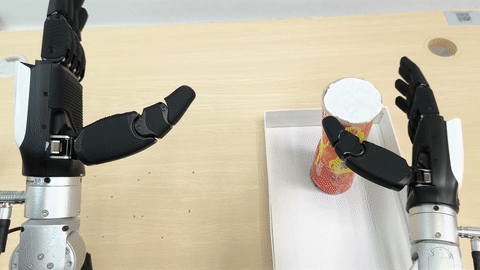
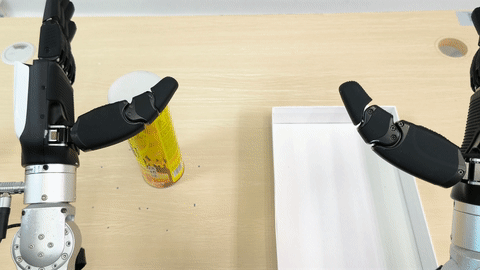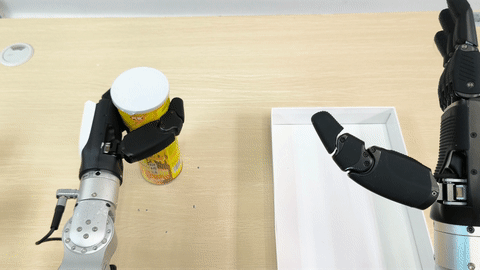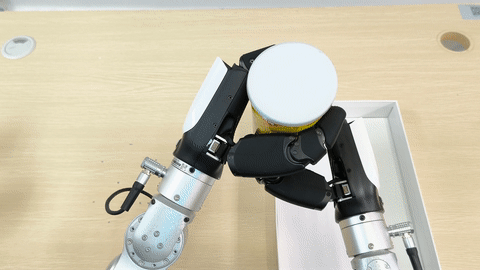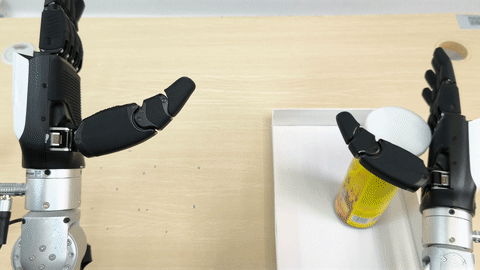
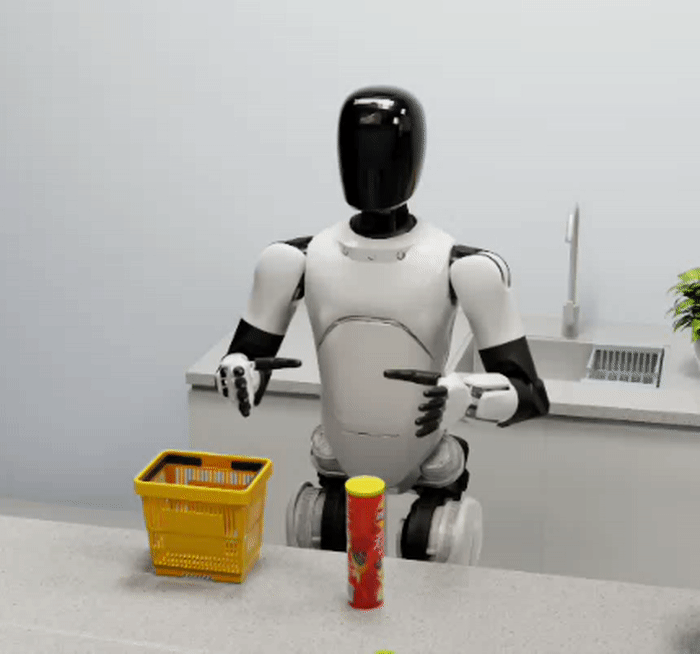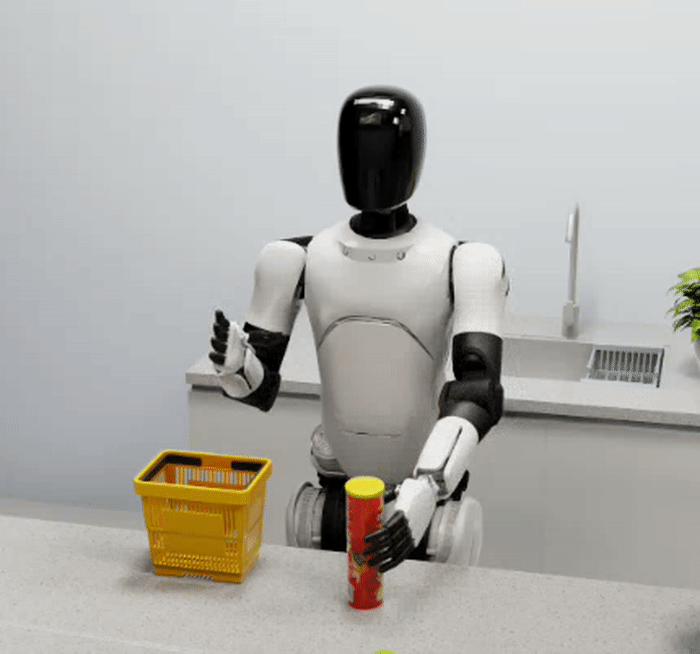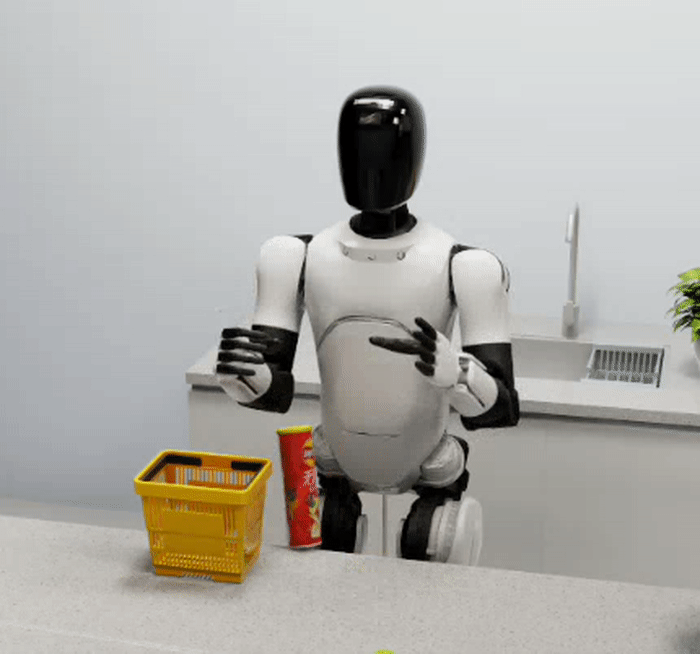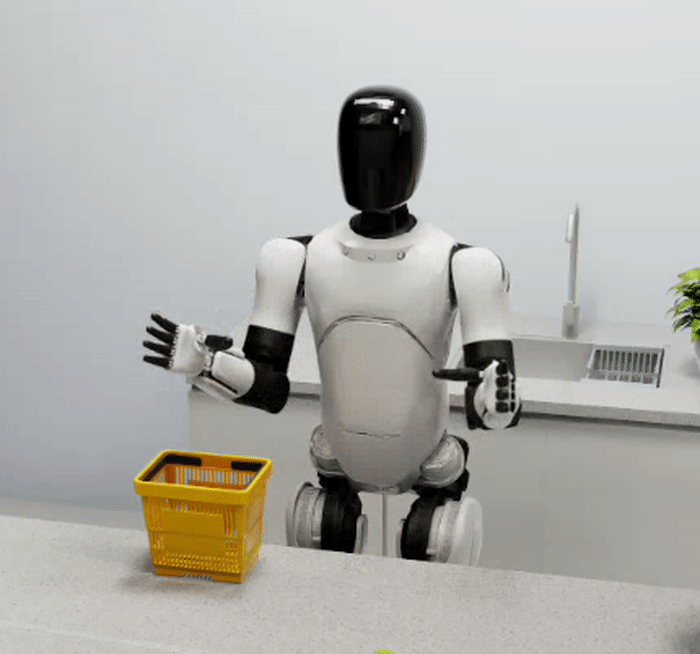
Direct comparison between the SeedOnly baseline and the Seed2Scale* policy (self-evolution) across representative manipulation tasks.

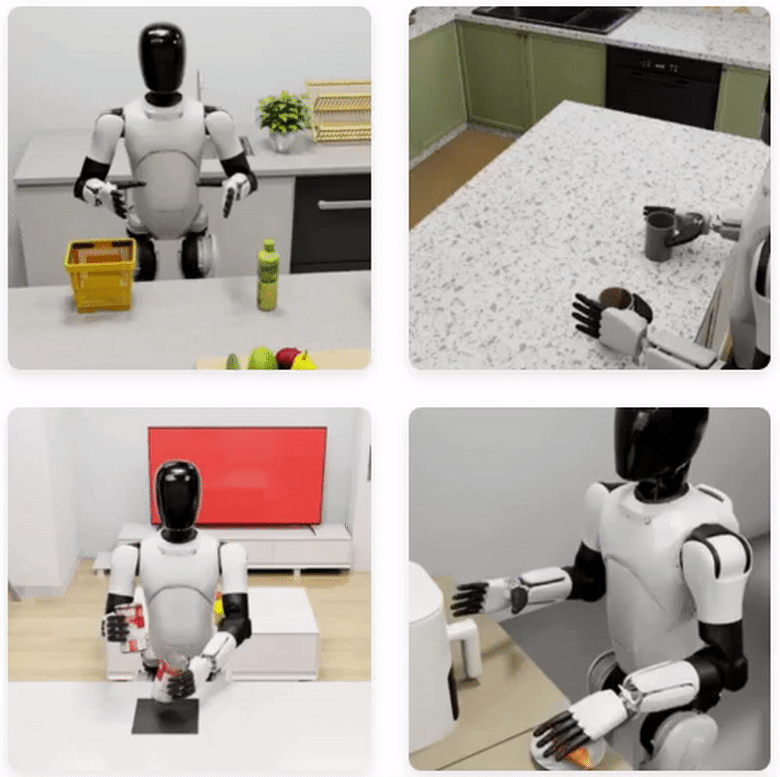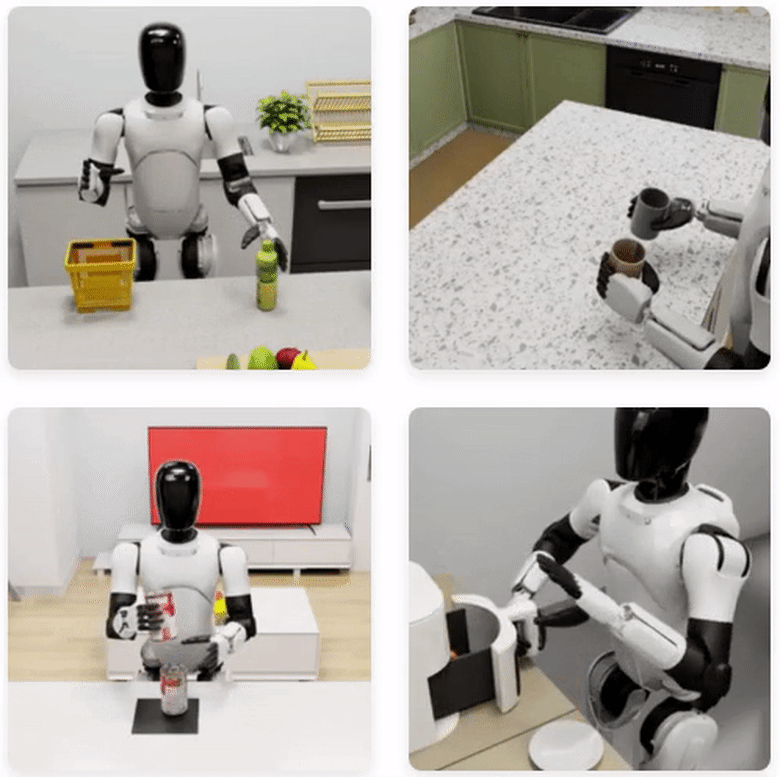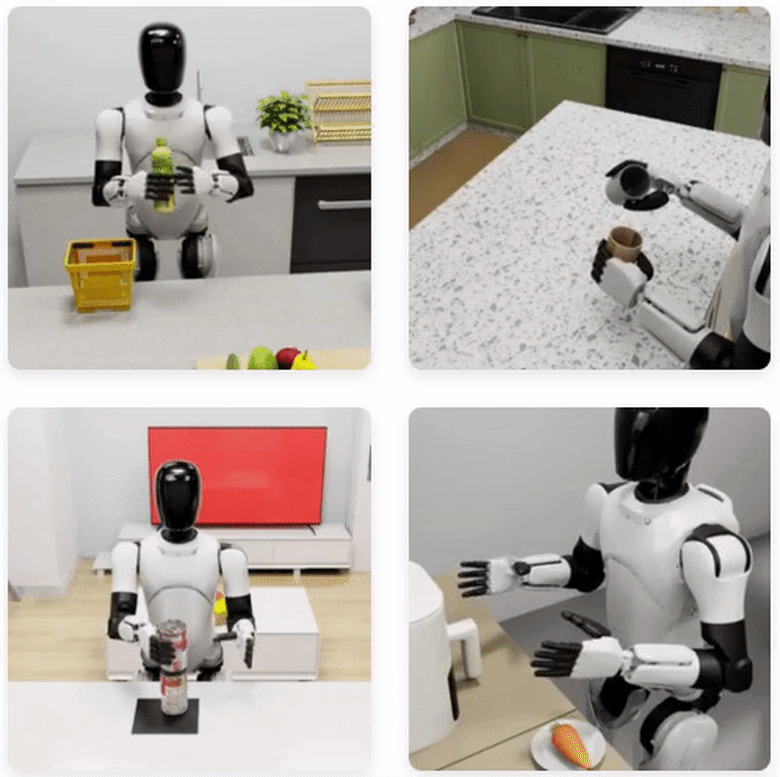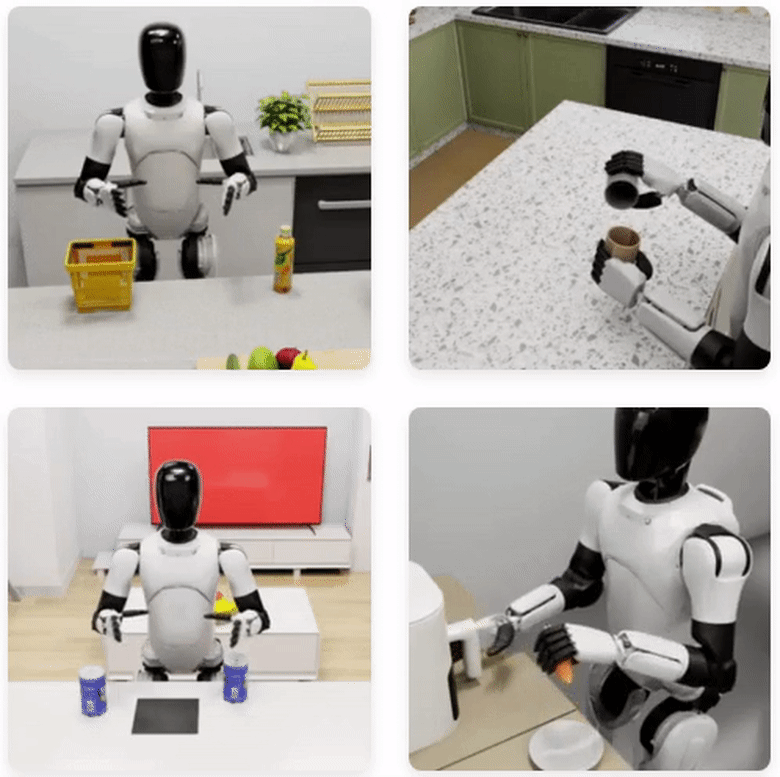
Kitchen Cleanup · Task 1 SEEDONLY SEED2SCALE*
Task 1 SeedOnly baseline failure
SeedOnly (4 demos)
Task 1 Seed2Scale success
Seed2Scale* (Ours)
Can Stacking · Task 4 SEEDONLY SEED2SCALE*
Task 4 SeedOnly baseline failure
SeedOnly (4 demos)
Task 4 Seed2Scale success
Seed2Scale* (Ours)
Seed2Scale* vs. MimicGen on GR-1 Tasks

Smoother Motion, Higher Success

Self-evolved trajectories are physically plausible and smooth. MimicGen's IK-based approach introduces severe high-frequency instability, yielding kinematically infeasible motions.

Wheel ManipulationMimicGen
MimicGen Wheel
Policy: 34.75% · Replay: 48.50%
Wheel ManipulationSeed2Scale*
Seed2Scale Wheel
Policy: 93.25% (+58.50) · Replay: 67.86%
Cylinder GraspingMimicGen
MimicGen Cylinder
Policy: 37.25% · Replay: 21.00%
Cylinder GraspingSeed2Scale*
Seed2Scale Cylinder
Policy: 66.00% (+28.75) · Replay: 86.96% (4.1×)
06 — Quantitative Results

Performance Metrics

Comprehensive evaluation across simulation and real-world tasks, demonstrating consistent scaling with only 4 seed demonstrations and zero-shot transfer to unseen scenes.

0%
Zero-shot real-world success (baselines fail completely)
0.00% → 75.38% · Pick-and-Place
0%
Average success on unseen scenes via Parallel Worlds
0.00% → 65.34% · 3 unseen worlds
0
Replay success over MimicGen (Cylinder Grasping)
21.00% → 86.96%
0
SuperTiny speed vs. Diffusion Policy
38ms vs 136ms inference

Agibot A2: Seen vs. Unseen Scene Generalization

Multi-task joint training · 4 seed demos per task · 396 independent trials · Seen = 10 parallel worlds (data generation) · Unseen = 3 disjoint worlds (evaluation only)

Task Evaluated on Seen Scenes Evaluated on Unseen Scenes
SeedOnly Seed2Scale* Seed2Scale SeedOnly Seed2Scale* Seed2Scale
Kitchen Cleanup24.63%71.43%68.50%0.00%0.00%75.51%
Cup-to-Cup Transfer23.50%64.14%60.61%0.00%0.00%61.62%
Can Stacking7.50%65.90%67.70%0.00%0.00%69.19%
Air Fryer Manipulation33.08%72.82%71.21%0.00%0.00%55.05%
Average22.18%68.57%67.01%0.00%0.00%65.34%

Seed2Scale* = self-evolution only (spatial generalization in the source world); Seed2Scale = full engine with Parallel Worlds (visual generalization). Both SeedOnly and Seed2Scale* score 0% on unseen scenes — scene diversity, not additional action supervision, is what unlocks generalization.

GR-1 Tasks: Seed2Scale* vs. MimicGen

MetricTaskMimicGenSeed2Scale*
Policy SuccessCylinder Grasping37.25%66.00%
Wheel Manipulation34.75%93.25%
Average36.00%79.63%
Replay SuccessCylinder Grasping21.00%86.96%
Wheel Manipulation48.50%67.86%
Average34.75%77.41%

Trajectory Quality (lower = better)

MetricExpert DemoMimicGenSeed2Scale*
Total Variation ↓1.323.681.34
Mean Abs. Jerk ↓0.00630.02610.0047
HF Power Ratio (%) ↓0.222.070.30
Motor joint action curves comparing Expert Demonstration, MimicGen and Seed2Scale
Fig. — Action Curve Comparison. Robot action curves generated by expert demonstration, MimicGen, and Seed2Scale*. Seed2Scale* closely tracks the Expert Demonstration in both amplitude and phase, while MimicGen diverges with severe high-frequency jitter — reflecting its higher Total Variation and Jerk scores in the table.
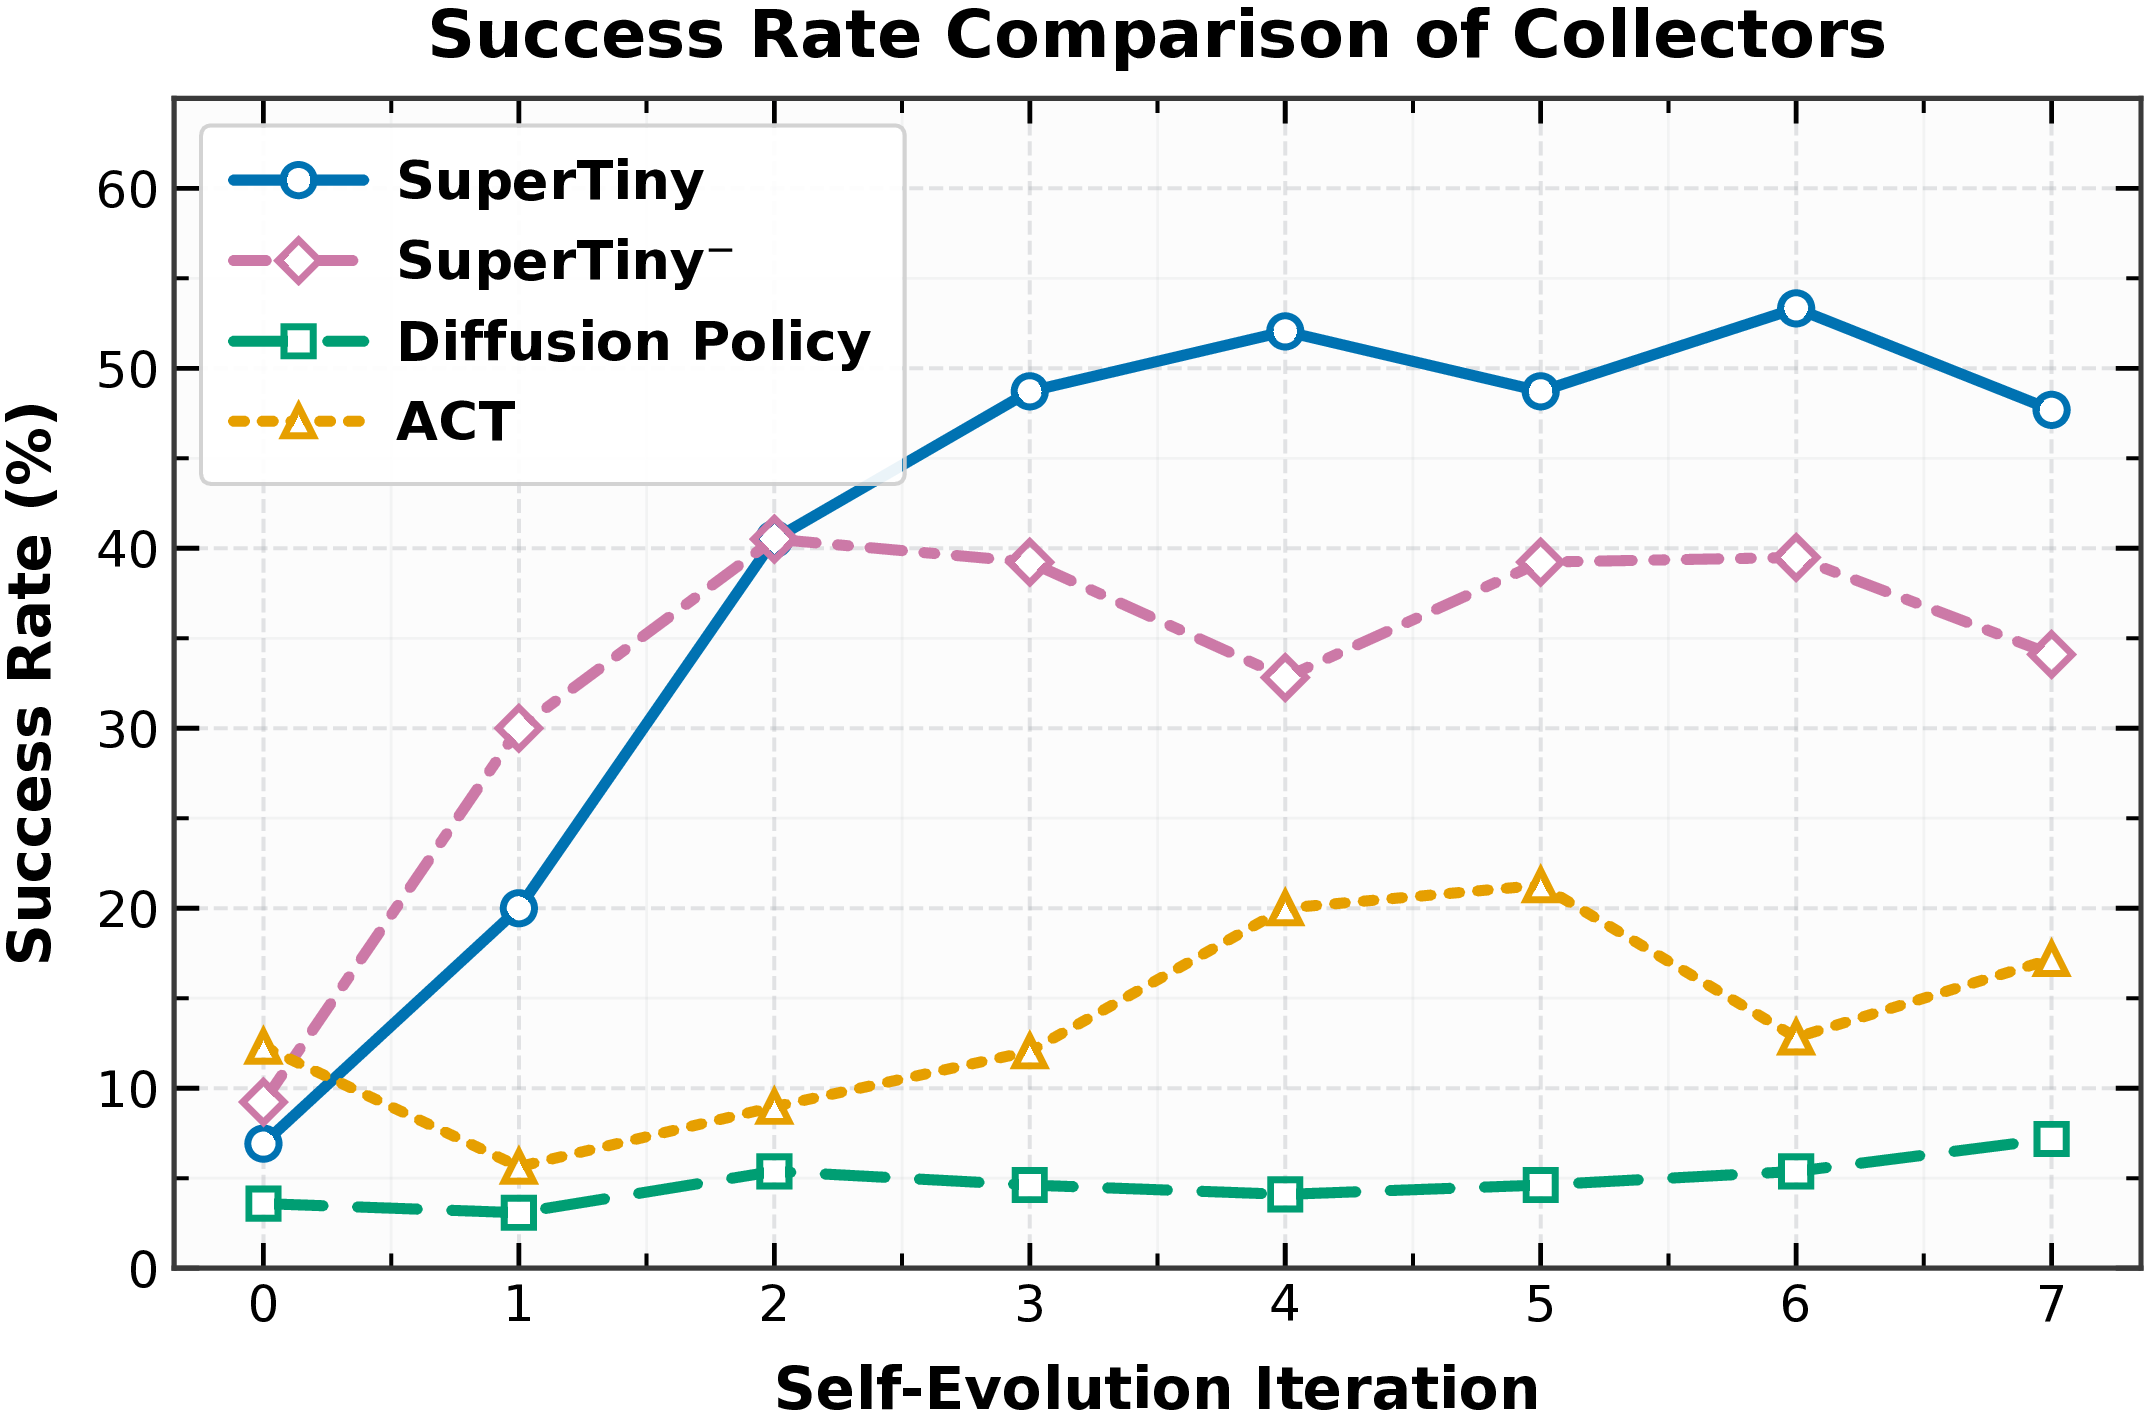
Ablation: Success Rate of SuperTiny, SuperTiny-minus, ACT and Diffusion Policy across self-evolution iterations
Fig. — Collector Comparison over Self-Evolution Iterations. SuperTiny (full model) converges faster and reaches the highest final success rate compared with its ablated variant SuperTiny⁻ (without VLV-based quality filtering), ACT, and Diffusion Policy. The gap to SuperTiny⁻ confirms that enforcing high trajectory quality — not just task completion — is essential for robust policy learning.
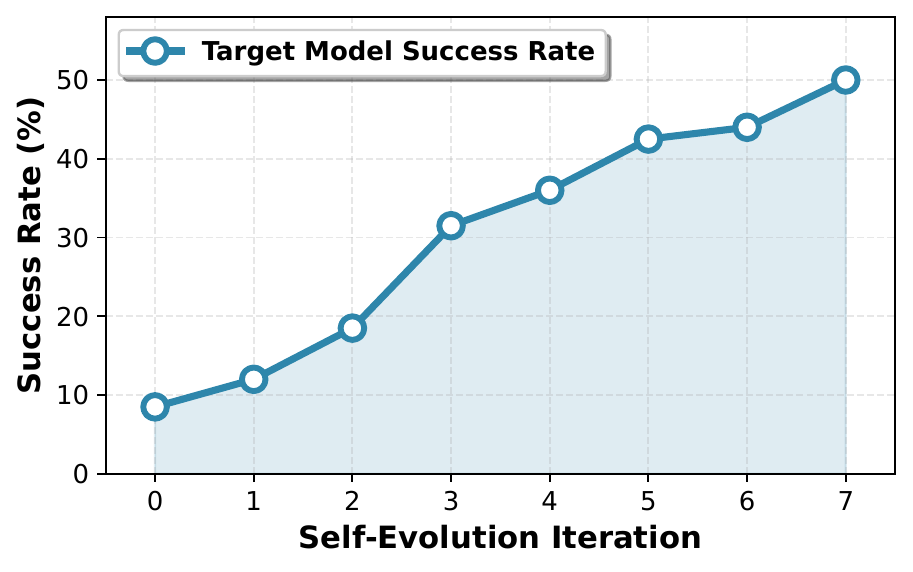
Scaling: Target Model (SmolVLA) vs. Self-Evolution Iteration
Can Stacking — single-task SmolVLA checkpoints across 8 iterations
Target model (SmolVLA) success rate across 8 self-evolution iterations on Can Stacking
Success Rate — SeedOnly vs. Seed2Scale*
Per-task comparison on Agibot A2 — Seen scenes
Kitchen Cleanup
Cup-to-Cup Transfer
Can Stacking
Air Fryer Manipulation
SeedOnly Seed2Scale* (Seen)
07 — Architecture

Model Specifications

Scale asymmetry by design — a tiny collector enables massive parallel exploration, a large frozen VLM ensures quality, and a mid-size target model generalizes across tasks.

SuperTiny VLA

Small-Scale Collector · πsmall
48M
  • Vision EncoderResNet-18 (3 cams)
  • Language EncoderT5-Small (frozen)
  • DecoderTransformer (cross-attn)
  • Action Chunk K30
  • Inference Time38.08 ms
  • Control Frequency26.3 Hz
  • EnsemblingExp. temporal (λ)
  • HardwareRTX 5090

Vision-Language Verifier

Large-Scale Evaluator · ΦVLV
32B
  • Base ModelQwen3-VL-32B
  • ModeFrozen (no fine-tuning)
  • Stage 1Rule-based Success Gate
  • Stage 2VLM Quality Scoring
  • Input 1Task instruction g
  • Input 2Rollout video Vτ
  • Input 3Reference video Vref
  • Output ScoreSτ ∈ [0, 10]
  • Threshold γFixed a priori (rubric)

Parallel Worlds

Trajectory-Conditioned Visual Generalization → Dfinal
10 Worlds
  • Worlds (A2 suite)10 scenes · some 3DGS
  • Seen / Unseen10 data · 3 eval-only
  • World Spec. CmAssets · poses · background · cameras
  • Object PosesSource-aligned across worlds
  • Projection Mm(τF)Control trajectory re-targeting
  • Feasibility CheckKinematics · collision · contact
  • Quality FilterVLV re-scoring after rollout
  • Real-World Setup7 sim scenes → real scene

SmolVLA Target Model

Final Policy · Conditional Flow Matching · πtarget
450M
  • Parameters450M
  • ObjectiveConditional Flow Matching
  • OptimizerAdamW
  • Learning Rate3 × 10⁻⁴
  • Training Steps100,000
  • Action Arch.CA + SA Action Expert
  • Training DataDfinal (curated)
  • DeploymentAgibot A2 / GR-1
SuperTiny VLA Architecture: Vision-Language-State encoding, conditioning memory, Transformer decoder with cross-attention, and Action Head with Temporal Ensembling
Fig. — SuperTiny VLA Architecture. The model integrates vision (ResNet-18), language (T5-Small), and robot state encodings into a unified conditioning memory Mt, which is processed by a lightweight Transformer decoder via cross-attention from learnable query embeddings to predict action chunks. Temporal ensembling ensures smooth and consistent control at 26.3 Hz.
08 — Multi-Task Demo

Four-Task Generalization

Multi-task joint training with cross-task knowledge transfer consistently outperforms single-task training. Evaluated on Seen scenes (10 parallel worlds) and Unseen scenes (3 disjoint worlds) on the Agibot A2 platform.

Seed2Scale four-task generalization

Kitchen Cleanup

Pick up the chip from the table, then place it into the basket. Tests precise grasping and placement from arbitrary positions beyond the 4 seed locations.

Seen: 68.50% · Unseen: 75.51%

Cup-to-Cup Transfer

Pour berries from the cup on the right into the cup on the left. Requires fine motor control and understanding of granular transfer dynamics with non-uniform objects.

Seen: 60.61% · Unseen: 61.62%

Can Stacking

Stack cans from both sides into the center and ensure they are placed stably. The hardest task for the 4-seed baseline, requiring complex spatial reasoning far beyond the seed demos.

Seen: 67.70% · Unseen: 69.19%

Air Fryer Manipulation

Grasp carrots from a plate, then open the air fryer and place the food inside. Tests multi-step manipulation with articulated objects, requiring precise door-handle grasping and coordinated placement.

Seen: 71.21% · Unseen: 55.05%
09 — Zero-Shot Sim2Real

From Simulation to the Real World

Policies trained exclusively in simulation — with no real-world data collection or fine-tuning — deployed zero-shot on a Pick-and-Place task, evaluated over 65 independent trials in an unseen real-world scene.

7
Parallel sim scenes for training data
+ real scene for evaluation
1,716
Episodes generated (225,217 frames)
vs. 4 episodes / 720 frames (SeedOnly)
65
Independent real-world trials
Unseen real scene
0
Real-world fine-tuning steps
Pure zero-shot transfer
ConfigurationEpisodesFramesZero-Shot Real-World Success
SeedOnly47200.00%
Seed2Scale*14219,7480.00%
Seed2Scale (3 scenes)43260,03927.69%
Seed2Scale (5 scenes)720100,06573.85%
Seed2Scale (7 scenes)1,716225,21775.38%

Success rate increases monotonically with scene diversity: from 0% in the single source world (SeedOnly and Seed2Scale*) to 27.69% with 3 scenes, 73.85% with 5 scenes, and 75.38% with 7 scenes — Parallel Worlds is the primary driver of zero-shot generalization to the real world.

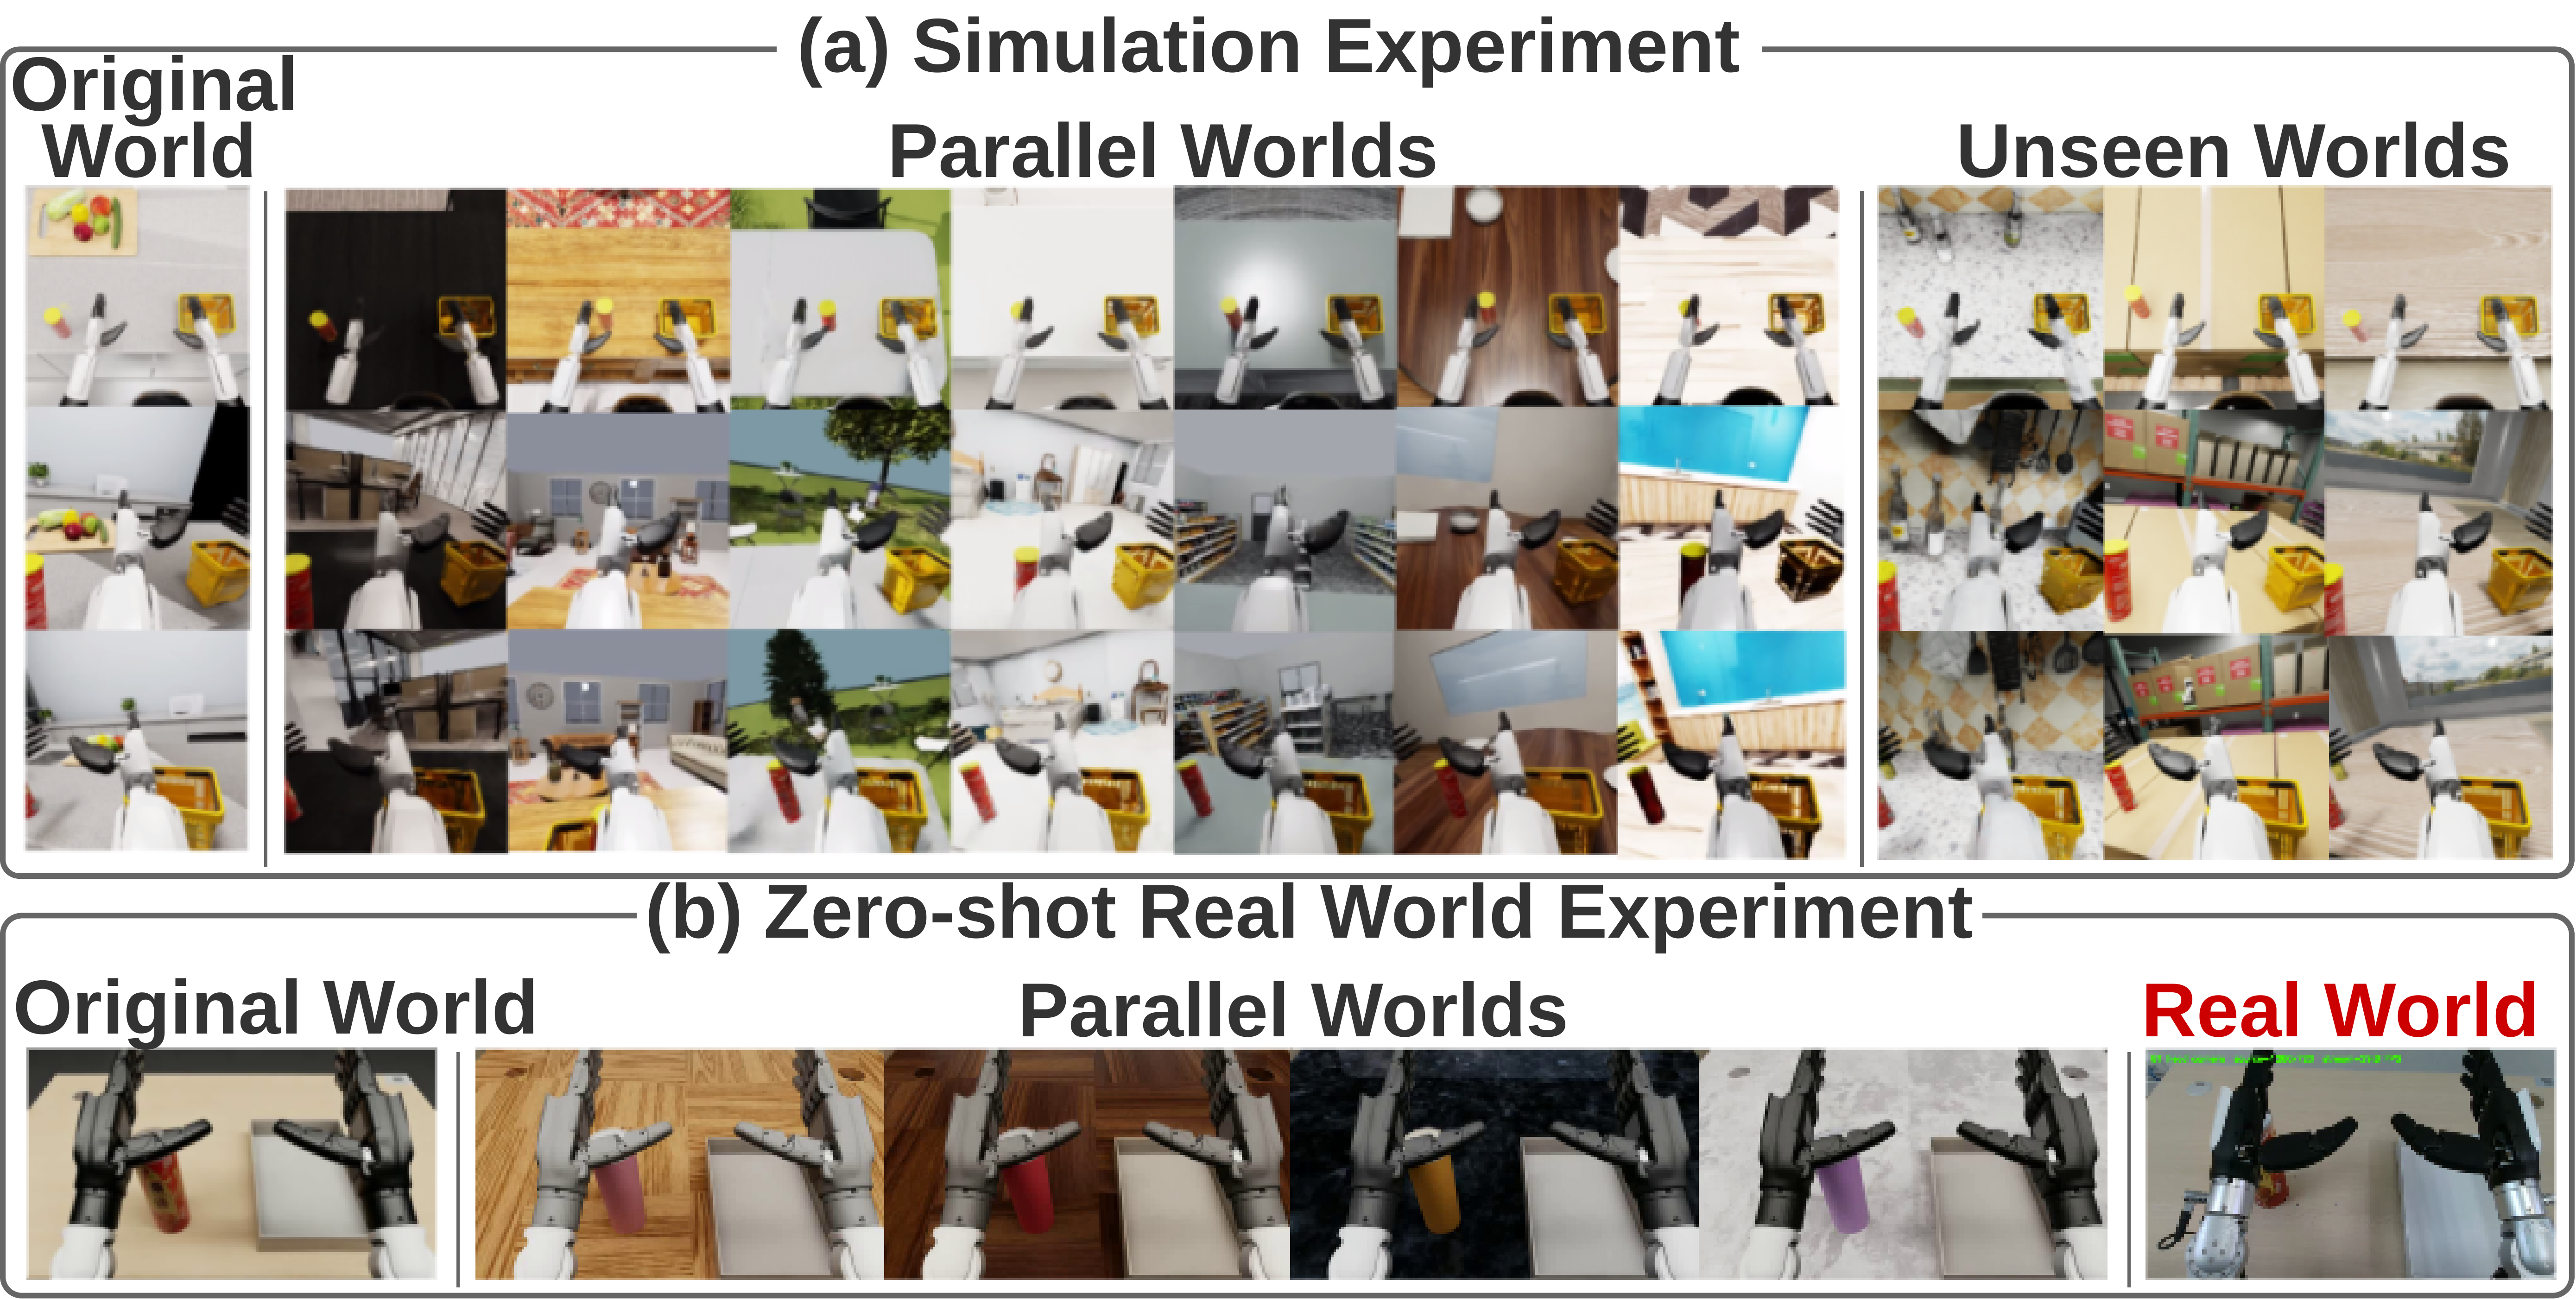
Parallel worlds for simulation experiments and zero-shot real-world experiments
Fig. — Parallel Worlds Overview. (a) Simulation experiment: the original world, the 10 parallel worlds projected from it (some constructed with 3D Gaussian Splatting), and the 3 unseen worlds reserved for evaluation. (b) Zero-shot real-world experiment: 7 parallel sim worlds and the real-world evaluation scene.
Real-World Demonstrations

Generalization to Unseen Scenes and Items

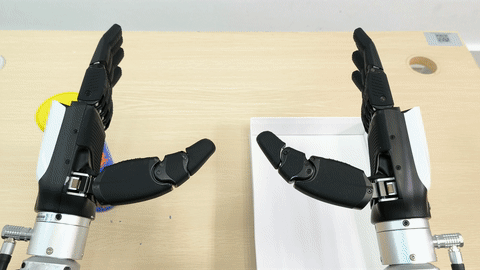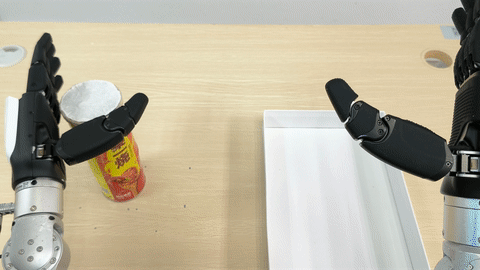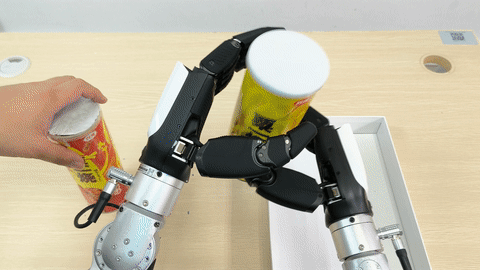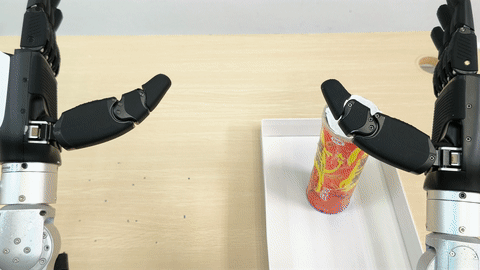
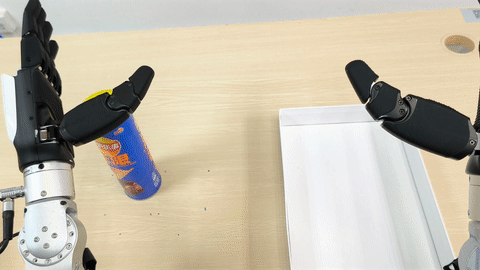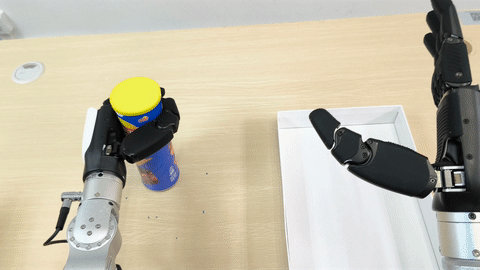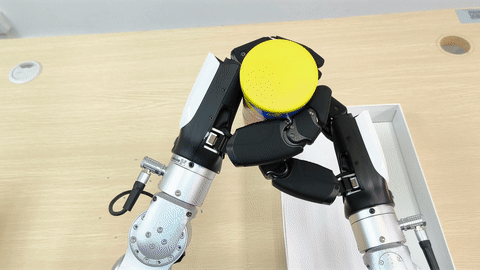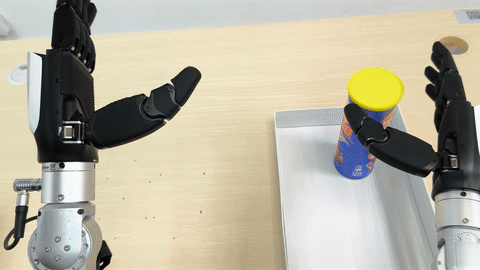
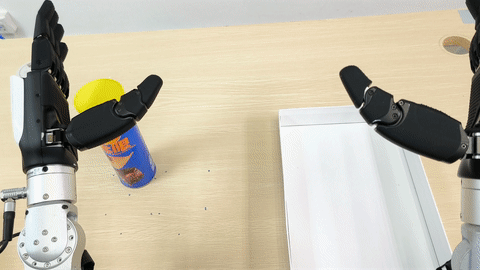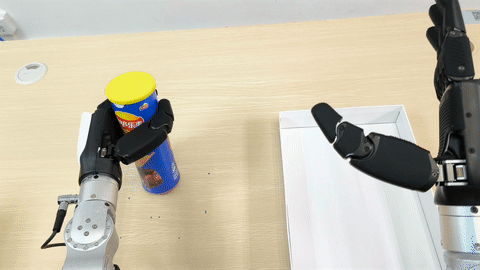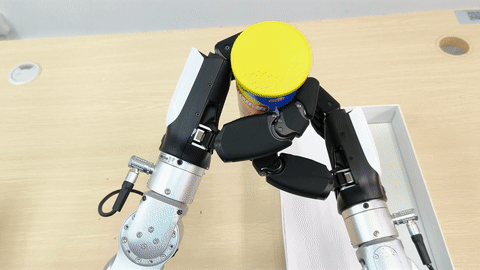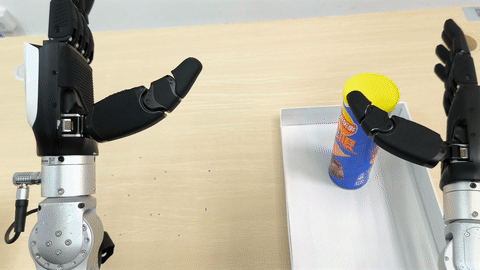
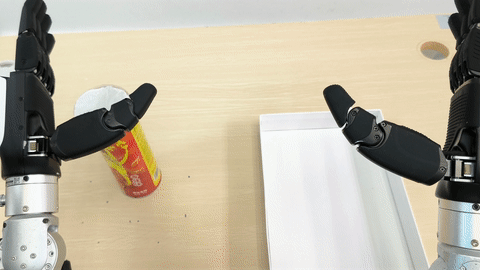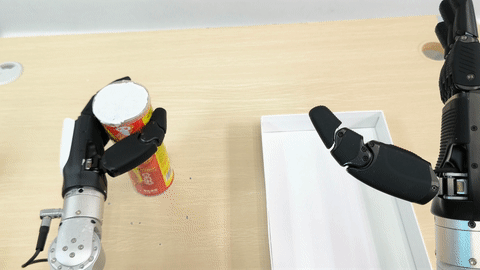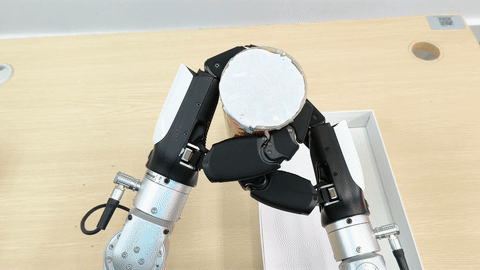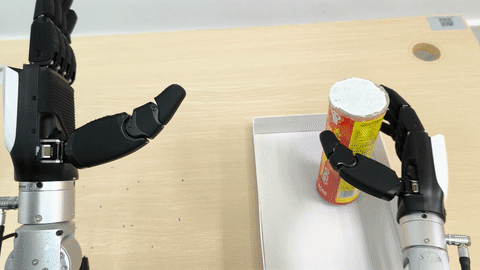
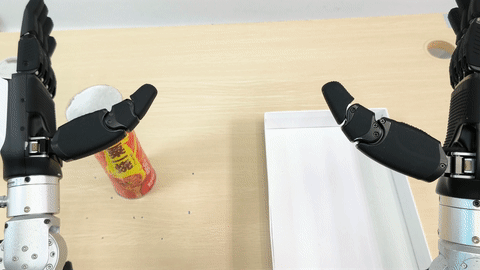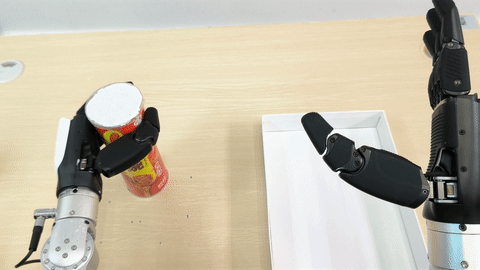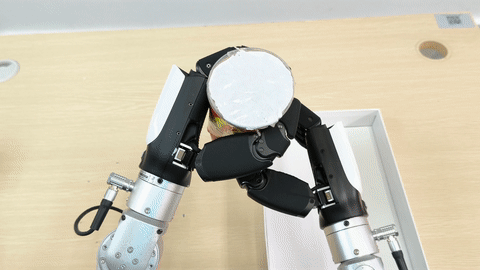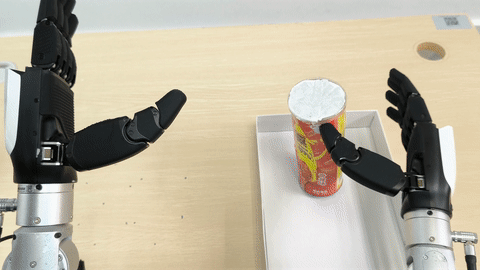
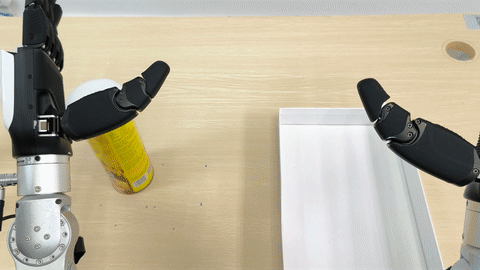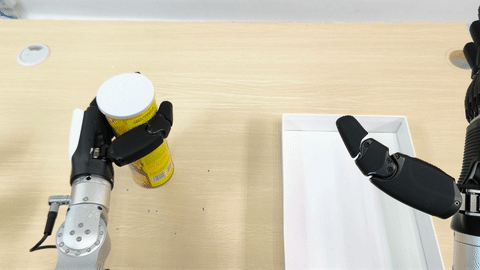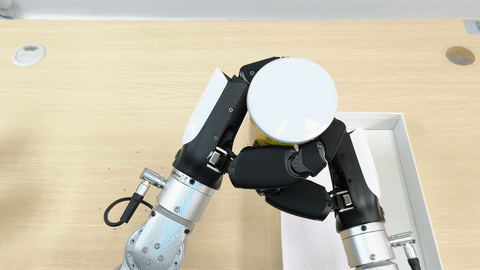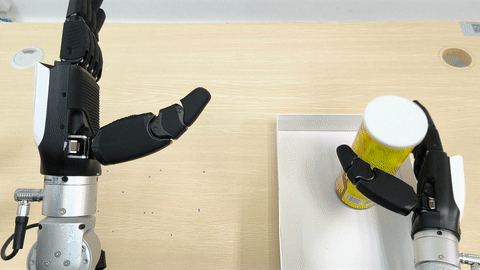
All demonstrations below are zero-shot: the policy is trained exclusively on simulation data generated by Seed2Scale (4 seed demos + parallel worlds) and deployed directly on the physical robot. Evaluation uses multiple target-item styles with evaluation areas aligned to the simulation data distribution, including configurations where multiple target items appear simultaneously at different locations.

Best zero-shot real-world pick-and-place results with 7-scene parallel-world training

Best zero-shot results of parallel-world training with 7 scenes — dexterous pick-and-place directly on the physical robot.

Zero-shot real-world pick-and-place demo 1
Zero-shot real-world pick-and-place demo 2
Zero-shot real-world pick-and-place demo 3
Zero-shot real-world pick-and-place demo 4
Zero-shot real-world pick-and-place demo 5
Zero-shot real-world pick-and-place demo 6
Zero-shot real-world pick-and-place demo 7
Zero-shot real-world pick-and-place demo 8
Zero-shot real-world pick-and-place demo 9
Zero-shot rollouts on the physical robot across diverse unseen target items (varied can and bottle styles) and spatial configurations — including multiple target items placed at different locations — demonstrating real-world generalization far beyond the source world, without any real-world fine-tuning.
10 — Paper

Full Paper

Submitted to ICRA 2027. Complete methodology, experimental setup, ablation studies, and analysis.

 Open in New Tab
11 — Acknowledgements

Special Thanks

Agibot A2 robot platform for large-scale experimental validation of Seed2Scale.

AGiBot collaboration banner

AGiBot provides A2 robot model and open-source support

We extend our sincere gratitude to AGiBot for providing the Agibot A2 robot model and open-source support that made the large-scale experimental validation of Seed2Scale possible.

12 — Citation

BibTeX

If you find Seed2Scale useful in your research, please consider citing our work.

seed2scale.bib
@article{tai2026seed2scale,
  title   = {Seed2Scale: A Self-Evolving Data Engine with Parallel Worlds Expansion for Scalable Robot Learning},
  author  = {Tai, Cong and Zheng, Zhaoyu and Long, Haixu and Wu, Hansheng and Wang, Jialiang and Long, Zhengbin and Xiang, Haodong and Wang, Shuyuan and Shi, Rong and Cui, Zhuo and Zhang, Shizhuang and Wang, He and Liu, Biao and Sun, Zhenzhe and Shen, Tao},
  journal = {arXiv preprint arXiv:2603.08260},
  year    = {2026}
}